


















Blogs
The Execution Layer for your Labeling-Ops
A unified execution layer that combines auto annotation, domain-qualified experts, and adaptive workflows to consistently deliver production-ready outcomes.
AI Pre-Labeling
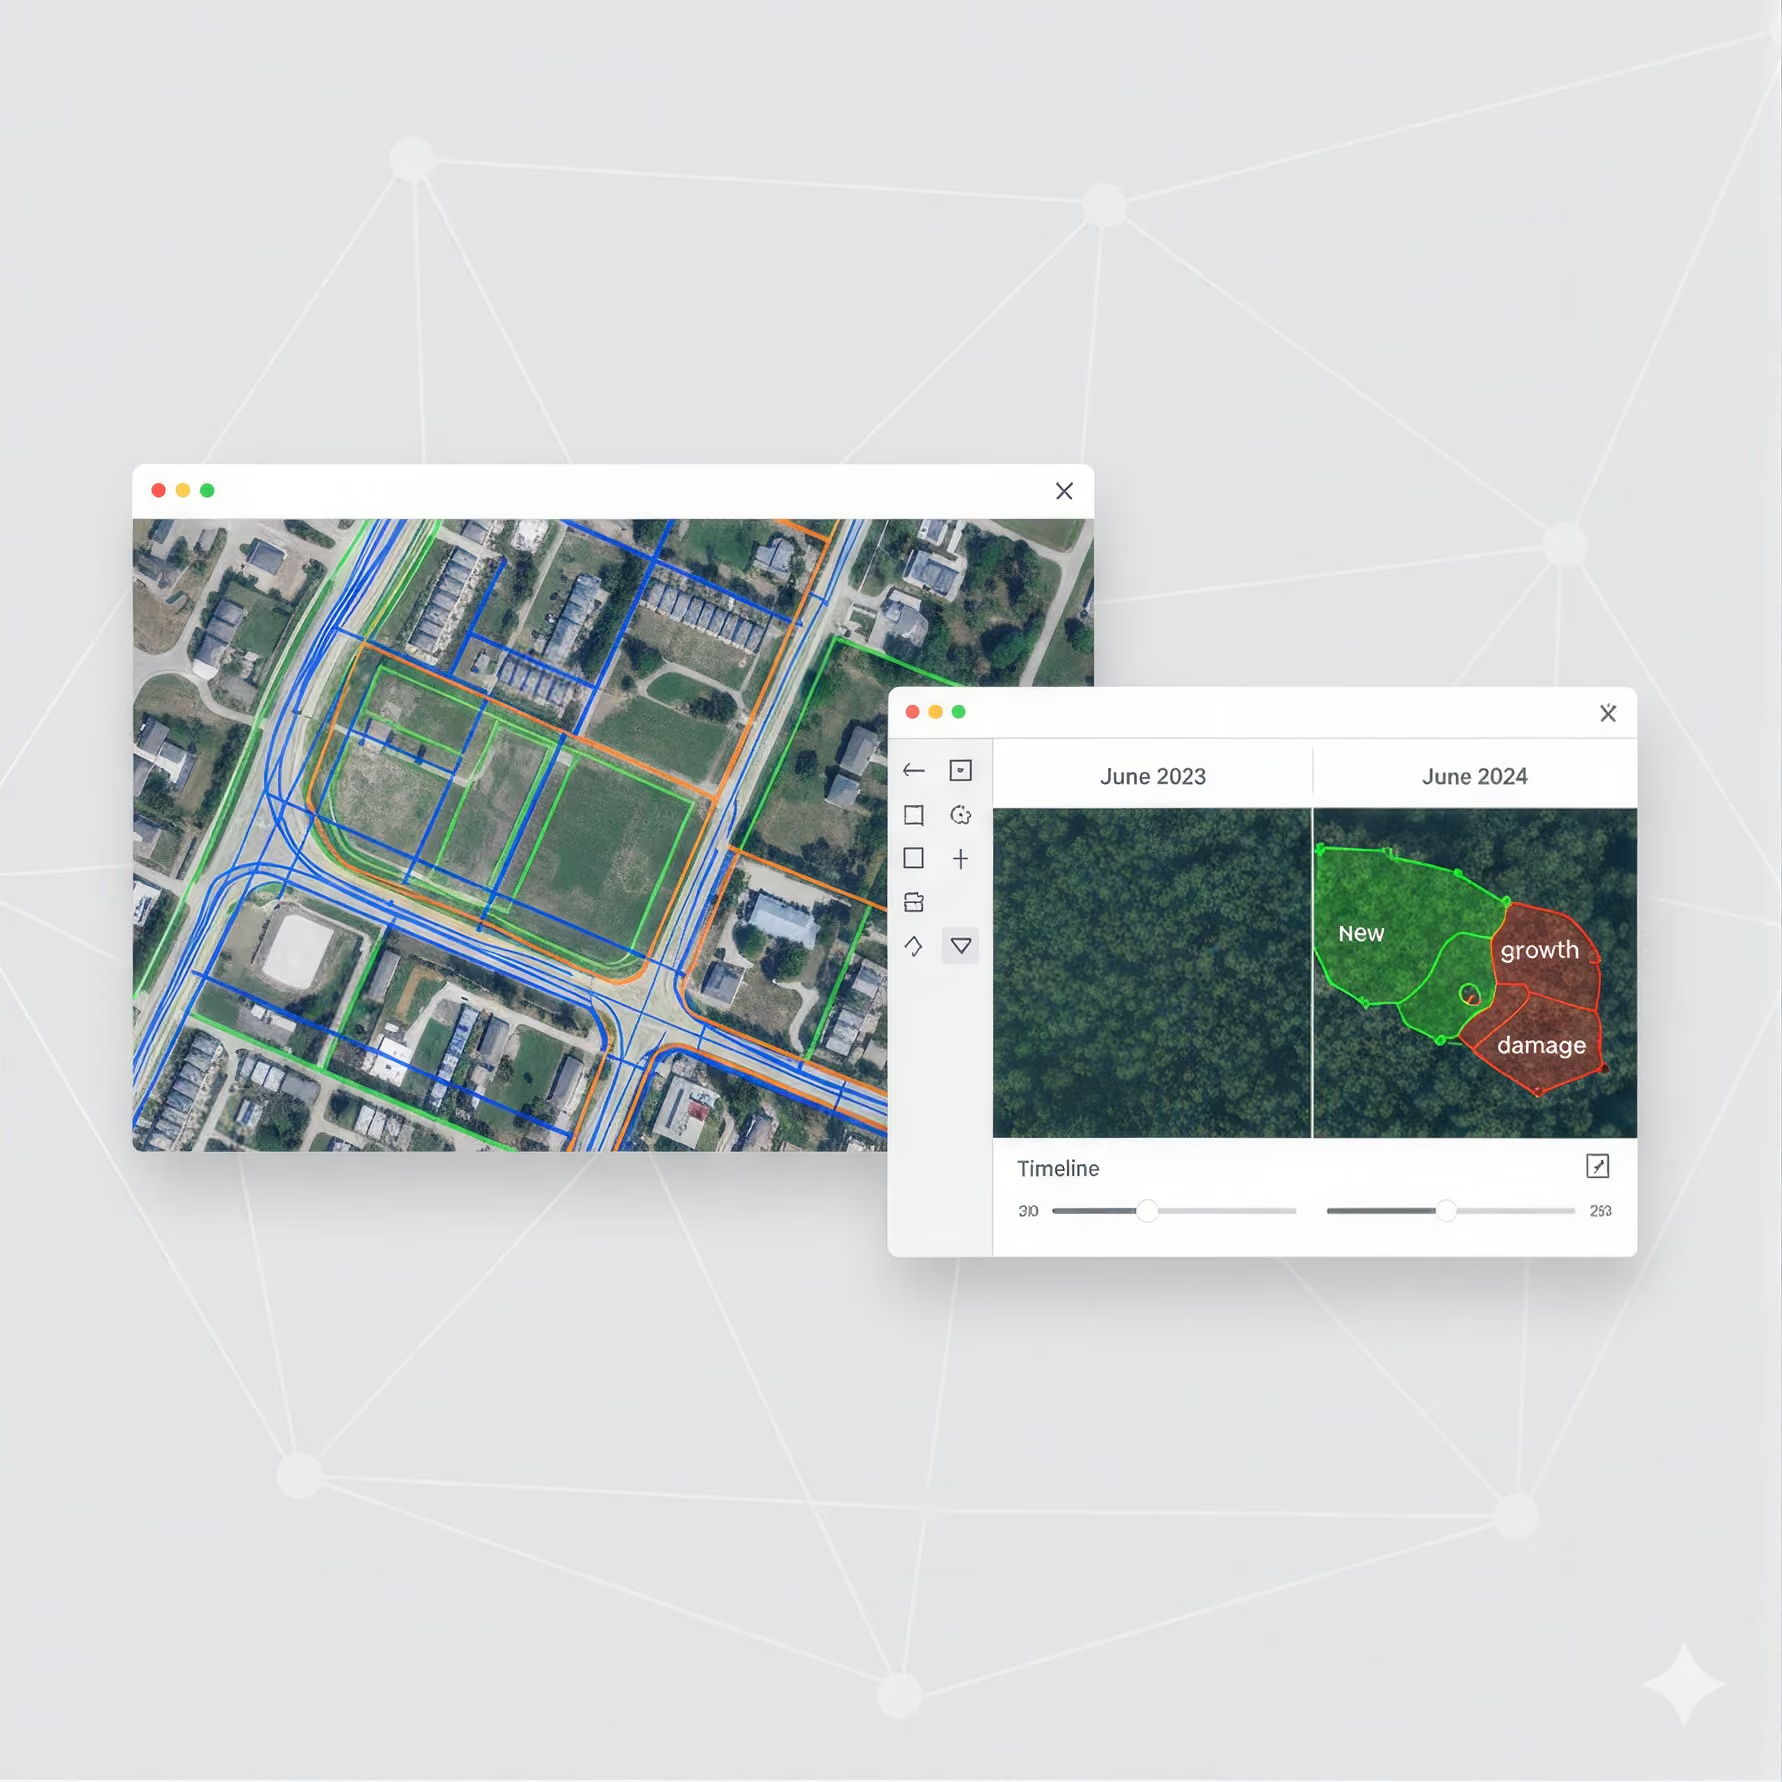
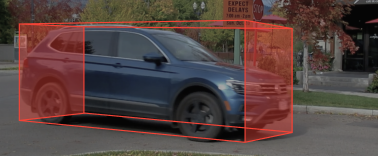
Pre-labeling that runs on task-matched models: SAM-3 for segmentation, YOLO v12 for detection, Mistral OCR for document extraction, Whisper-V3 and Google STT v2/Chirp for audio, with confidence-scored outputs routed to human review only where the model is uncertain. Swap models per task without re-architecting your pipeline.
View more

Workflow Orchestration
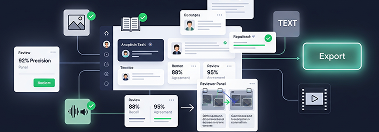
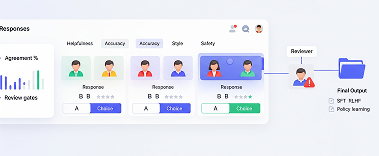
Task allocation runs on model/reviewer affinity, not a flat queue, each task goes to whichever model or specialist is calibrated for it. Maker-Checker and Consensus review sit on top as configurable QC layers, and every decision is versioned and traceable back to the model or reviewer that made it.
View more

Qualified Human Expertise
Specialists are qualified per task type before they touch your data: assessed, trained, certified, then monitored against live accuracy metrics, with a defined path to upskill into harder edge cases. Reviewers aren't generalists reassigned across projects; they're matched to the data type they were certified on.
View more